TRPO
Topics: Reinforcement Learning
Introduction
Trust Region Policy Optimization (TRPO) is an on-policy RL algorithm that can be used to train a stochastic policy with either discrete or continuous action spaces. The idea is that TRPO updates the policy by taking the largest possible step while satisfying a constraint between the old and new policy expressed in terms of a Kullback-Leibler Divergence. The reason for using a KL divergence constraint, is that, in regular policy gradient, the old and new policy are close in parameter space, but not necessarily in terms of the probability distributions. A small difference in parameter space might have a large effect on the probability distribution and consequently on performance. By using KL divergence, TRPO keeps the old and new distributions close and tends to improve performance quickly and monotonically (1)
Equations
The theoretical optimization problem that TRPO solves is the following:
where is an estimator of the advantage function
The intuition behind the term that in the maximization is as follows:
- if , then the action is on average better than . Therefore, should be increased, which means maximizing the positive value in the parentheses.
- if , then the action is worse than the average . Therefore, should be decreased, and the problem is a maximization of a negative value
Approximations
The theoretical optimization problem of TRPO is difficult to work with, so approximations are made to get answers quickly
TODO: Go into the details of the approximations from the paper and (1)
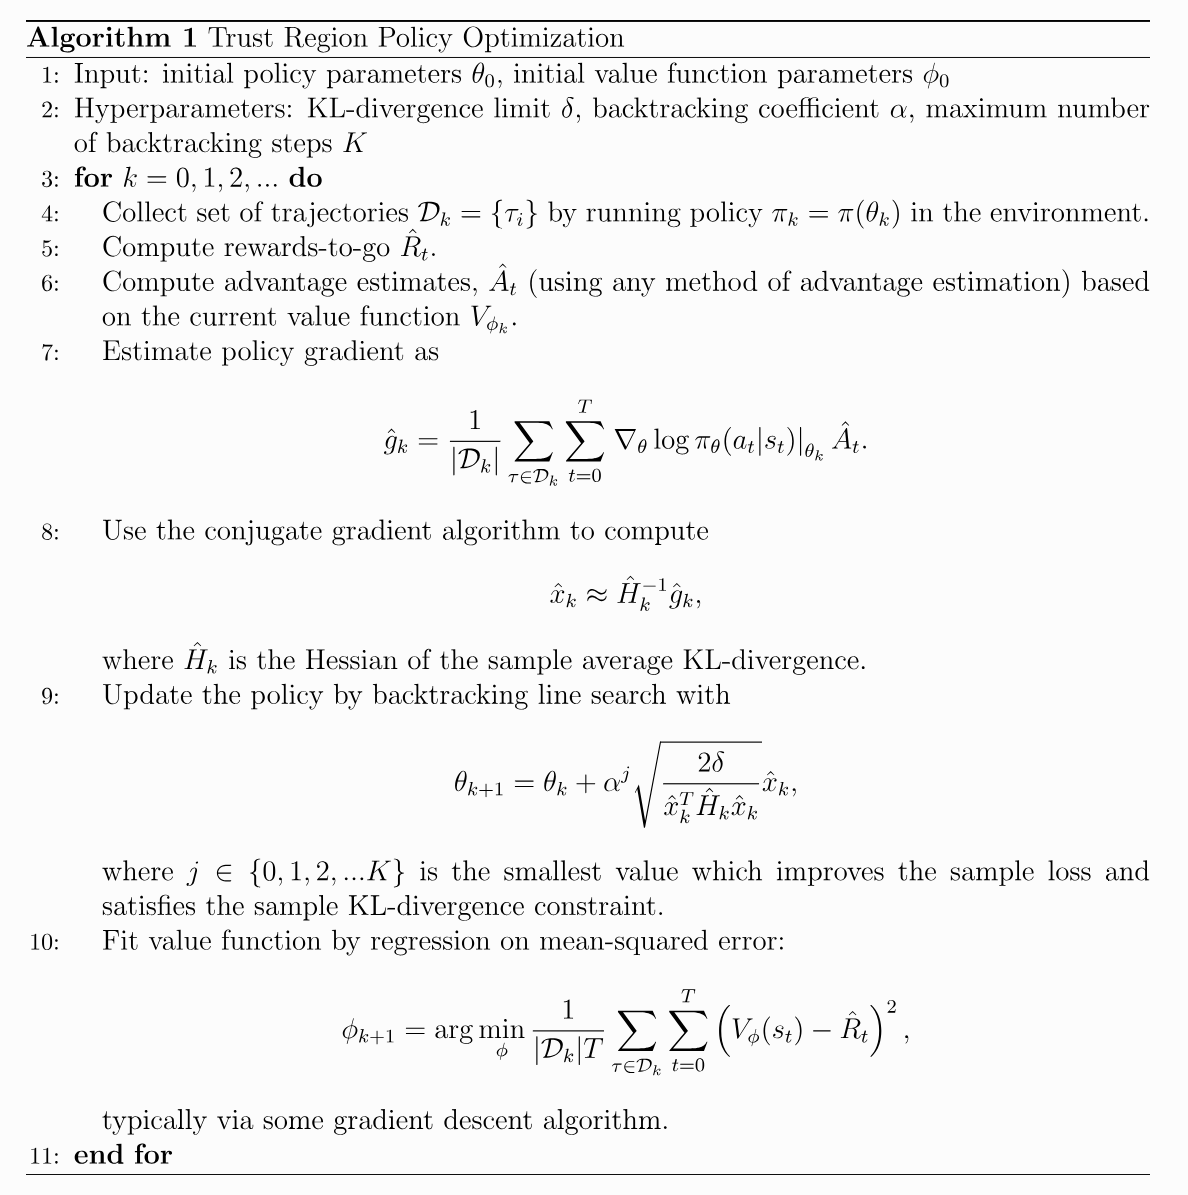
Pseudocode
References
Backlinks
Notes that reference this page.
Connections
Direct relationships to this note.