Double Q-Learning
Topics: Reinforcement Learning
Concept
Double Q-Learning is an improvement of the Q-Learning algorithm. The main motivation behind the idea of Double Q-Learning is the problem of Overestimation in Q-Learning. In the update equation of Q-Learning, the maximum over all actions is taken. This maximization leads to the overestimation of Q-values, and since Q-Learning is a boot-strapping algorithm (learns estimates from estimates), this overestimation causes the agent to learn a poor policy.
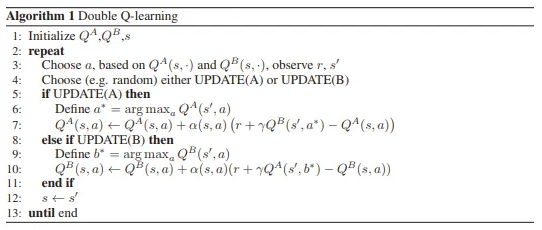
The Double Q-Learning algorithm uses 2 tables of Q-value estimates and . The idea is that, the table that is being updated is used to select the maximizing action, while the other table is used to evaluate the action. The tables are updated interchangeably ( probability).
In other words, in order to update , the maximizing action is selected from and is evaluated using . On the other hand, in order to update , the maximizing action is selected from and is evaluated using .
After training, is used as the unbiased estimator.
Pseudocode
Below is the pseudocode of the Double Q-Learning algorithm (1).
References
Backlinks
Notes that reference this page.
Connections
Direct relationships to this note.